Assessing Phylogenetic Signal Effect Size
Mark A. Conaway
Introduction: Phylogenetic Comparative Methods
Fitting linear models, and performing statistical analyses in
general, to assess biological hypotheses regarding closely-related
species presents a problem to the researcher. Standard statistical
models rely on the assumption that observations are independent and
identically distributed (iid). Mathematically, this means that the
Gaussian error of an iid dataset can be expressed as an identity matrix.
However, when species are closely related (for example within the same
genus) by phylogeny, we expect observations taken on them to be more
similar than those taken from more distantly-related species. This means
that error in this case cannot be expressed as an identity matrix. In
other words, observations taken from closely related species cannot be
considered independent, or identically distributed. Phylogenetic
Comparative Methods (PCM) is an analytical toolkit consisting of
methodologies designed to account for this issue of non-independence of
observations. With this toolkit, researchers can construct models and
perform other related analyses with non independent observations by
subsequently \(conditioning\) those
observations on a phylogeny. Under this PCM analytical umbrella are Phylogenetic ANOVA, Phylomorphospace, Phylogenetic Signal, and Evolutionary Rates,
all of which can be performed using functions in
geomorph.
Phylogenetic Signal Effect Size
Phylogenetic signal refers to the extent to which phenotypic similarity in a dataset is associated with phylogenetic relatedness. This signal is expected to be higher among the most closely-related species but, in cases where relationships among species are not as close, but still potentially significant, phylogenetic signal can be used to determine whether one’s subsequent analyses should take phylogeny into account (Adams, 2014). Perhaps more importantly, quantifying phylogenetic signal across several traits can help to show which aspects of the phenotype are more evolutionarily labile.
The physignal.z function is distinct from physignal in that phylogenetic signal is
computed from the standardized log-likelihood in a distribution
generated from randomization of residuals in a permutation procedure
(RRPP). Based on the procedure described in Collyer et al., (2022), this
function estimates phylogenetic signal with an optimized version of
Pagel’s Lambda (\(\hat{\lambda}\)),
which can be generated using a number of different protocols (see
below). The result is an estimation of phylogenetic signal with more
robust statistical properties that can be compared with other effect
sizes of different sets of traits.
physignal.z()
- \(A\): A matrix (n x [p x k]) or 3D array (p x k x n) containing Procrustes shape variables for a set of specimens
- \(phy\): A phylogenetic tree of class phylo - see read.tree in library ape
- \(lambda\): An indication for how lambda should be optimized. This can be a numeric value between 0 and 1 to override optimization. Alternatively, it can be one of four methods: burn-in (“burn”); mean lambda across all data dimensions (“mean”); use a subset of all data dimensions where phylogenetic signal is possible, based on a front-loading of phylogenetic signal in the lowest phylogenetically aligned components (“front”); or use of all data dimensions to calculate the log-likelihood in the optimization process (“all”). See Details for more explanation.
- \(iter\): Number of iterations for significance testing
- \(seed\): An optional argument for setting the seed for random permutations of the resampling procedure. If left NULL (the default), the exact same P-values will be found for repeated runs of the analysis (with the same number of iterations). If seed = “random”, a random seed will be used, and P-values will vary. One can also specify an integer for specific seed values, which might be of interest for advanced users.
- \(tol\): A value indicating the magnitude below which phylogenetically aligned components should be omitted. (Components are omitted if their standard deviations are less than or equal to tol times the standard deviation of the first component.) See ordinate for more details.
- \(PAC.no\): The number of phylogenetically aligned components (PAC) on which to project the data. Users can choose fewer PACs than would be found, naturally.
- \(print.progress\): A logical value to indicate whether a progress bar should be printed to the screen. This is helpful for long-running analyses.
- \(verbose\): Whether to include verbose output, including phylogenetically-aligned component analysis (PACA), plus K, lambda, and the log-likelihood profiles across PAC dimensions.
Example Analysis: Phylogenetic Signal Effect Size in Shape
To illustrate the use of this function, we test for phylogenetic signal in the head shape of plethodon salamanders. The data used here are available with geomorph as part of the ‘plethspecies’ dataset.
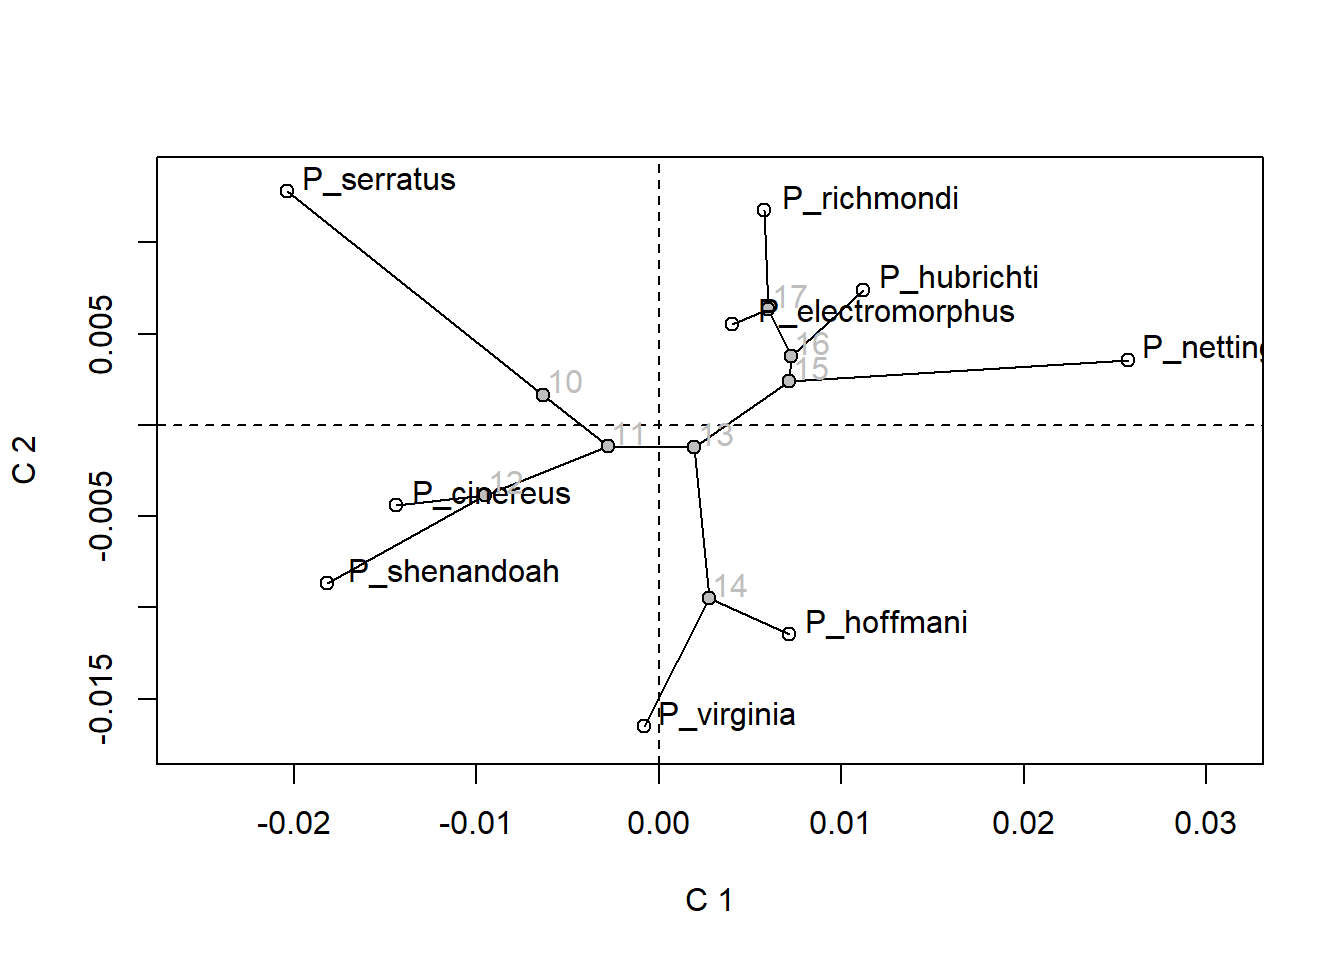
PS.shape <- physignal(A = lmks$coords, phy = plethspecies$phy, iter=999)summary:
summary(PS.shape)##
## Call:
## physignal(A = lmks$coords, phy = plethspecies$phy, iter = 999)
##
##
##
## Observed Phylogenetic Signal (K): 0.9573
##
## P-value: 0.008
##
## Based on 1000 random permutations
##
## Use physignal.z to estimate effect size.plot:
plot(PS.shape)
plot(PS.shape$PACA, phylo = TRUE)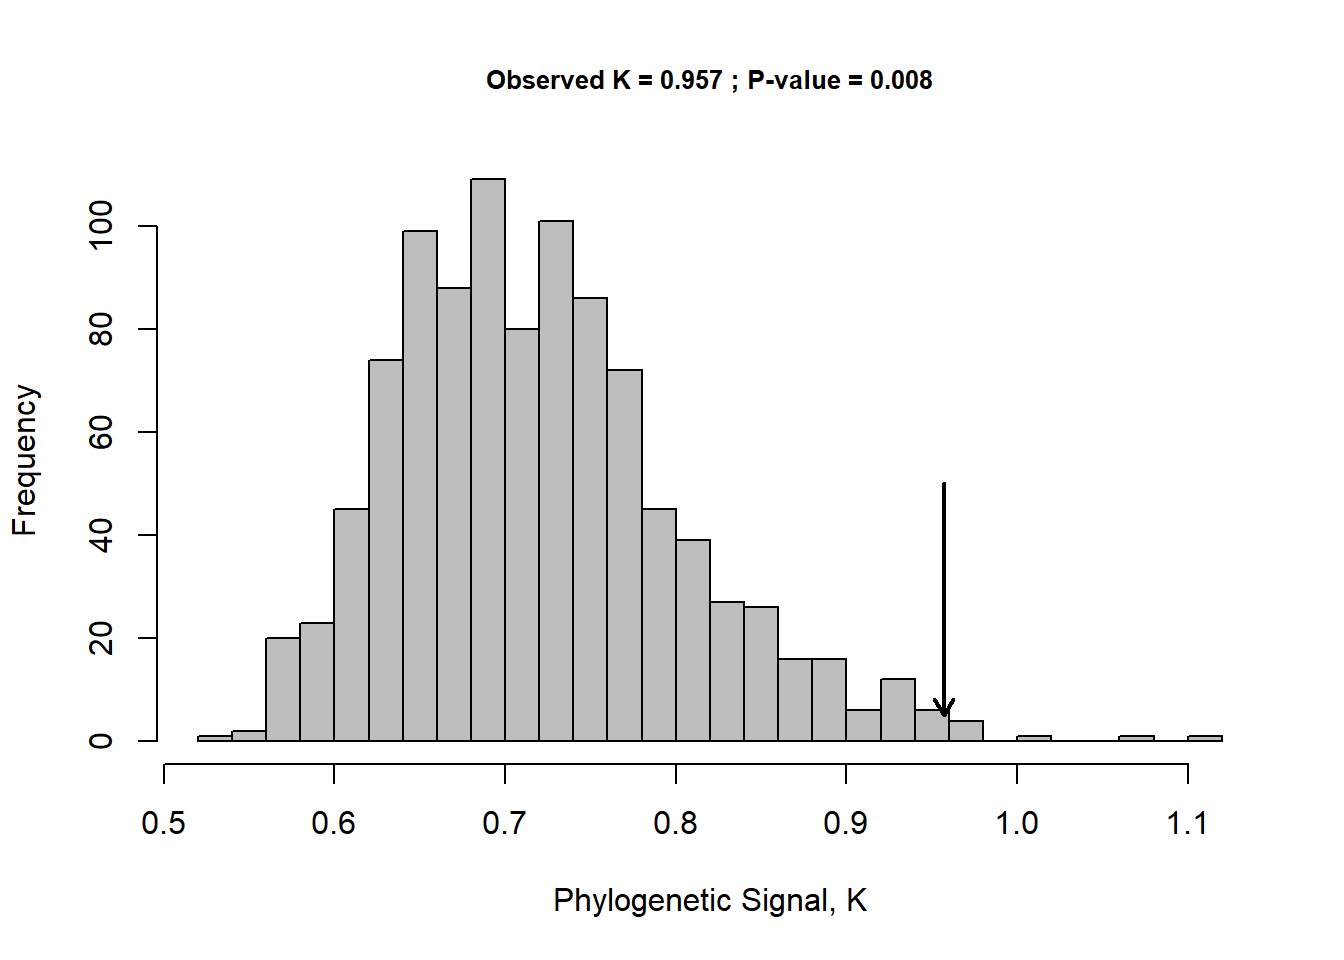
PS.shape$K.by.p## [1] 1.5034858 1.4253457 1.1610972 1.0762048 1.0010464 0.9746155 0.9623519 0.9572991 0.9572991Example Analysis: Phylogenetic Signal Effect Size in Size
To calculate the phylogenetic signal effect size for size, rather than shape, simply replace the input Procrustes coordinates for the ‘A’ argument with the centroid sizes for one’s data ($Csize):
PS.size <- physignal(A = lmks$Csize, phy = plethspecies$phy, iter=999)summary(PS.size)##
## Call:
## physignal(A = lmks$Csize, phy = plethspecies$phy, iter = 999)
##
##
##
## Observed Phylogenetic Signal (K): 0.7098
##
## P-value: 0.477
##
## Based on 1000 random permutations
##
## Use physignal.z to estimate effect size.plot(PS.size)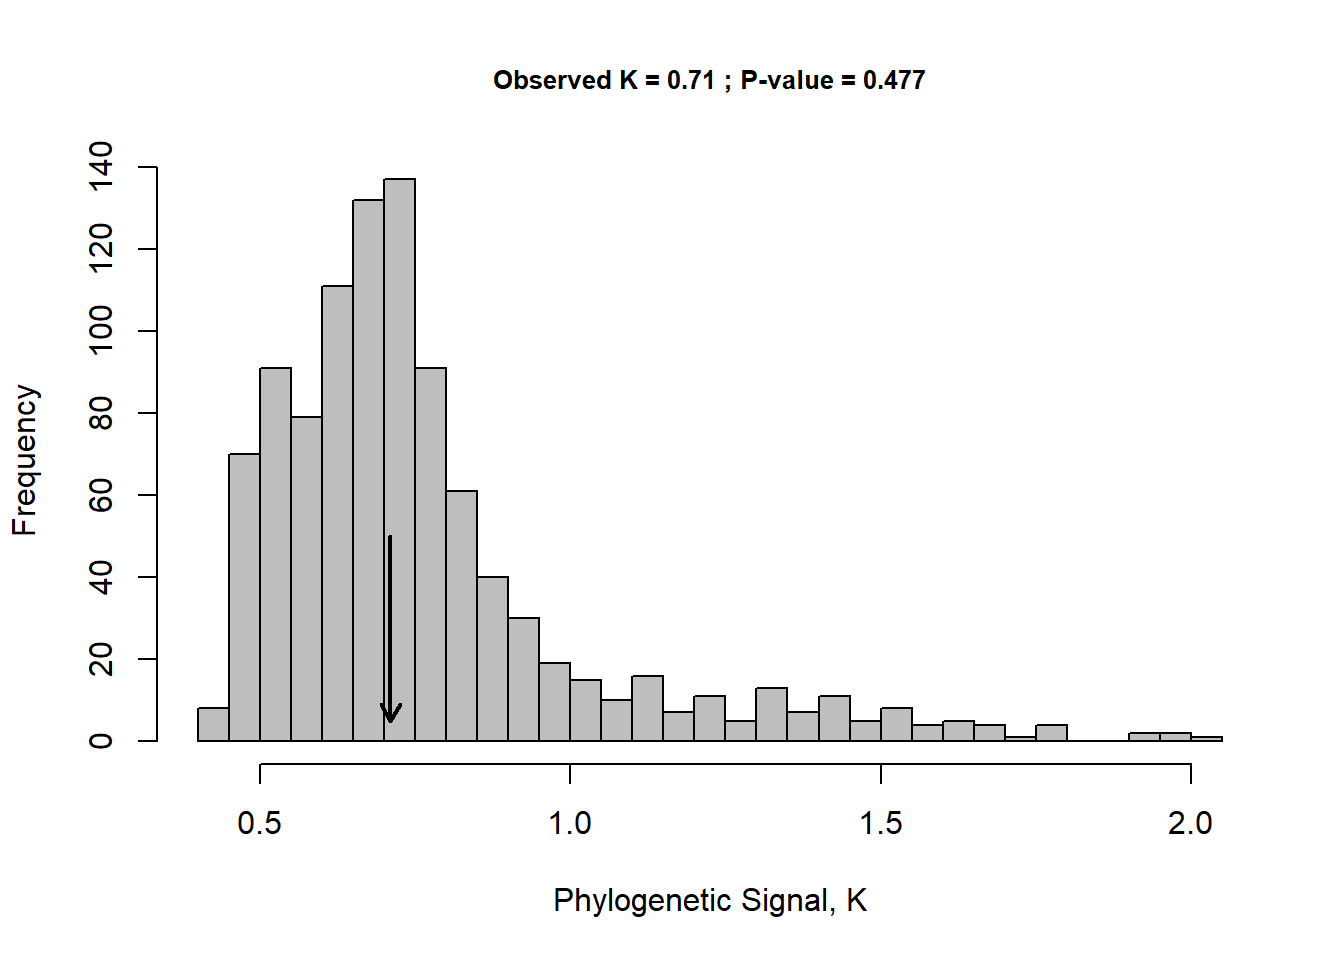
This function returns a list object containing the following which can be accessed individually using the $ operator:
physignal.z() Output
- \(Z\): Phylogenetic signal effect size.
- \(pvalue\): The significance level of the observed signal.
- \(random.detR\): The determinants of the rates matrix for all random permutations.
- \(random.logL\): The log-likelihoods for all random permutations.
- \(lambda\): The optimized lambda value.
- \(K\): The multivariate K value.
- \(PACA\): A phylogenetically aligned component analysis, based on OLS residuals.
- \(K.by.p\): The multivariate K value in 1, 1:2, 1:3, …, 1:p dimensions, for the p components from PACA.
- \(lambda.by.p\): The optimized lambda in 1, 1:2, 1:3, …, 1:p dimensions, for the p components from PACA.
- \(logL.by.p\): The log-likelihood in 1, 1:2, 1:3, …, 1:p dimensions, for the p components from PACA.
- \(permutations\): The number of random permutations used in the resampling procedure.
- \(opt.method\): Method of optimization used for lambda.
- \(opt.dim\): Number of data dimensions for which optimization was performed.
- \(call\): The matched call
Important Note! To compare multiple phylogenetic
signal effect sizes, see the tutorial for the compare.physignal.z function.