Comparing Rates of Shape Evolution on Phylogenies (Single Trait)
Mark A. Conaway
Introduction: Phylogenetic Comparative Methods
Fitting linear models, and performing statistical analyses in
general, to assess biological hypotheses regarding closely-related
species presents a problem to the researcher. Standard statistical
models rely on the assumption that observations are independent and
identically distributed (iid). Mathematically, this means that the
Gaussian error of an iid dataset can be expressed as an identity matrix.
However, when species are closely related (for example within the same
genus) by phylogeny, we expect observations taken on them to be more
similar than those taken from more distantly-related species. This means
that error in this case cannot be expressed as an identity matrix. In
other words, observations taken from closely related species cannot be
considered independent, or identically distributed. Phylogenetic
Comparative Methods (PCM) is an analytical toolkit consisting of
methodologies designed to account for this issue of non-independence of
observations. With this toolkit, researchers can construct models and
perform other related analyses with non independent observations by
subsequently \(conditioning\) those
observations on a phylogeny. Under this PCM analytical umbrella are Phylogenetic ANOVA, Phylomorphospace, Phylogenetic Signal, and Evolutionary Rates,
all of which can be performed using functions in
geomorph.
Comparing Evolutionary Rate Among Groups
The rate of evolutionary change, or the diversification of phenotypic
traits, is an important question in evolutionary biology and related
fields. In particular, evolutionary rate can be examined as a means to
understand the processes responsible for evolutionary diversification.
Traditionally, rates of evolution have been calculated using univariate
data. However, the evolutionary rate functions in geomorph
allow the user to calculate rates of evolution from multivariate, and
even high dimensional data - that is, data where the number of trait
dimensions exceeds the number of observations (taxa).
The compare.evol.rates function, allows the user to
calculate and compare rates of evolution on a phylogeny among different
species or groups. This function follows the protocol of Adams (2014)
whereby, after the data (a 3D array of Procrustes
coordinates) are conditioned on the phylogeny, evolutionary rate is
calculated as the sum of squared distances between those
phylogenetically-transformed data and the origin, divided by the number
of trait dimensions to provide an average rate across trait dimensions.
Finally evolutionary rates are compared based on the outer-product
matrix of between-species differences after phylogenetic
transformation.
compare.evol.rates()
- \(A\): A 3D array (p x k x n) containing GPA-aligned coordinates for all specimens, or a matrix (n x variables)
- \(phy\): A phylogenetic tree of class phylo - see read.tree in library ape
- \(gp\): A factor array designating group membership for individuals
- \(iter\): Number of iterations for significance testing
- \(seed\): An optional argument for setting the seed for random permutations of the resampling procedure. If left NULL (the default), the exact same P-values will be found for repeated runs of the analysis (with the same number of iterations). If seed = “random”, a random seed will be used, and P-values will vary. One can also specify an integer for specific seed values, which might be of interest for advanced users.
- \(method\): One of “simulation” or “permutation”, to choose which approach should be used to assess significance.
- \(print.progress\): A logical value to indicate whether a progress bar should be printed to the screen. This is helpful for long-running analyses.
Example Analysis
To illustrate usage of this function, we will use landmark data from
several plethodontid salamander species found in the dataset
“plethspecies,” included with geomorph. In this example, we
compare evolutionary rates for the given landmark data between
endangered species and non-threatened species.
gp.end<-factor(c(0,0,1,0,0,1,1,0,0))
names(gp.end)<-plethspecies$phy$tipER<-compare.evol.rates(A = lmks$coords, phy = plethspecies$phy,
method = "simulation",gp = gp.end,iter = 999, print.progress = F)summary:
summary(ER)##
## Call:
##
##
## Observed Rate Ratio: 1.8372
##
## P-value: 0.124
##
## Effect Size: 1.2768
##
## Based on 1000 random permutations
##
## The rate for group 0 is 1.79641730182344e-06
##
## The rate for group 1 is 3.30041132572866e-06This summary includes the Observed Rate Ratio, which represents the relative difference in evolutionary rates between groups (the test statistic), as well as a P-value and effect size for this statistic. Additionally, the summary provides invidual evolutionary rates for each group.
Finally, results of this function can also be visualized using the base R functionplot:
plot(ER)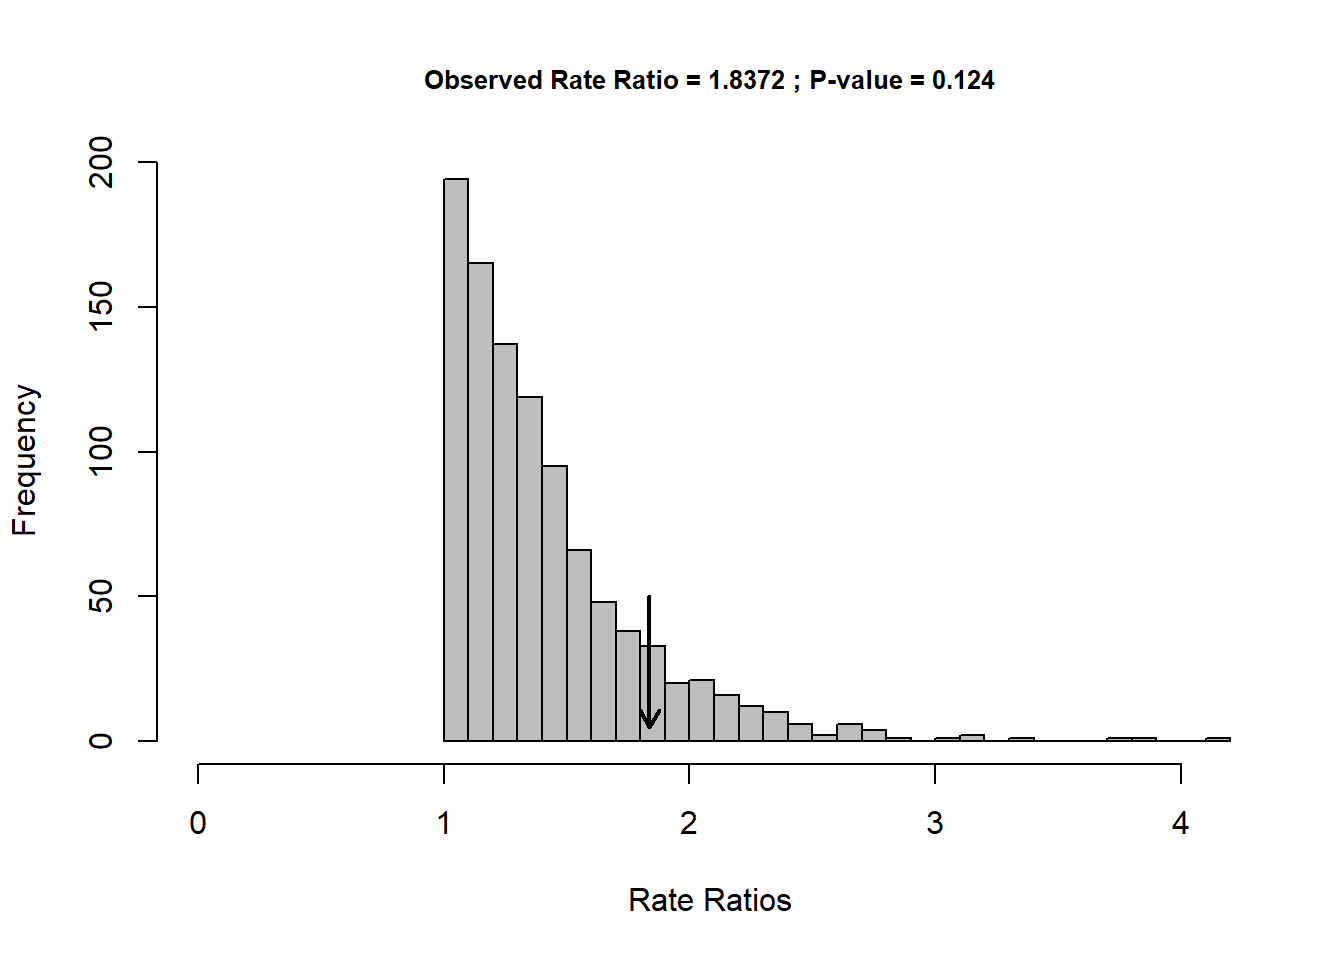
This function generates an object of class “evolrate” which is a list, whose objects can be accessed using the $ operator.
compare.evol.rates() Output
- \(sigma.d.ratio\): The ratio of maximum to minimum net evolutionary rates.
- \(P.value\): The significance level of the observed ratio.
- \(Effect.Size\): The multivariate effect size associated with sigma.d.ratio.
- \(sigma.d.gp\): The phylogenetic net evolutionary rate for each group of species on the phylogeny.
- \(random.sigma\): The sigma values found in random permutations of the resampling procedure.
- \(permutations\): The number of random permutations used.
Important Note!
To compare the evolutionary rates among multiple sets of \(traits\) (as opposed to groups, or
species), see the tutorial for compare.multi.evol.rates